Alternative Title: The tragic story of how I got trapped making slides with latex.
Typically after giving a presentation at least one person will approach me and ask if they could have access to my custom latex template to make slides with beamer that don’t look rubbish.
When recently looking at some reaction data, I was confronted with the problem of atom-to-atom mapping (AAM) and what tools are available to tackle it. AAM refers to the process of mapping individual atoms in reactants to their corresponding atoms in the products, which is important for defining a reaction template and identifying which bonds are being formed and broken. This has many downstream uses for computational chemists, such as for reaction searching and forward and retrosynthesis planning1. The problem is that many reaction databases do not contain these mappings, and annotation by expert chemists is impractical for databases containing thousands (or more) data points.
Today’s post builds on my earlier blogpost on how to turn a SMILES string into an extended-connectivity fingerprint using RDKit and describes an interesting and easily implementable modification of the extended-connectivity fingerprint (ECFP) featurisation. This modification is based on representing the atoms in the input compound at a different (and potentially more useful) level of abstraction.
We remember that each binary component of an ECFP indicates the presence or absence of a particular circular subgraph in the input compound. Circular subgraphs that are structurally isomorphic are further distinguished according to their inherited atom- and bond features, i.e. two structurally isomorphic circular subgraphs with distinct atom- or bond features correspond to different components of the ECFP. For chemical bonds, this distinction is made on the basis of simple bond types (single, double, triple, or aromatic). To distinguish atoms, standard ECFPs use seven features based on the Daylight atomic invariants [1]; but there is also another less commonly used and often overlooked version of the ECFP that uses pharmacophoric atom features instead [2]. Pharmacophoric atom features attempt to describe atomic properties that are critical for biological activity or binding to a target protein. These features try to capture the potential for important chemical interactions such as hydrogen bonding or ionic bonding. ECFPs that use pharmacophoric atom features instead of standard atom features are called functional-connectivity fingerprints (FCFPs). The exact sets of standard- vs. pharmacophoric atom features for ECFPs vs. FCFPs are listed in the table below.
In RDKit, ECFPs can be changed to FCFPs extremely easily by changing a single input argument. Below you can find a Python/RDKit implementation of a function that turns a SMILES string into an FCFP if use_features = True and into an ECFP if use_features = False.
# import packages
import numpy as np
from rdkit.Chem import AllChem

# define function that transforms a SMILES string into an FCFP if use_features = True and into an ECFP if use_features = False
def FCFP_from_smiles(smiles,
                     R = 2,
                     L = 2**10,
                     use_features = True,
                     use_chirality = False):
    """
    Inputs:

    - smiles ... SMILES string of input compound
    - R ... maximum radius of circular substructures
    - L ... fingerprint-length
    - use_features ... if true then use pharmacophoric atom features, if false then use standard DAYLIGHT atom features
    - use_chirality ... if true then append tetrahedral chirality flags to atom features

    Outputs:
    - np.array(feature_list) ... FCFP/ECFP with length L and maximum radius R
    """

    molecule = AllChem.MolFromSmiles(smiles)
    feature_list = AllChem.GetMorganFingerprintAsBitVect(molecule,
                                                         radius = R,
                                                         nBits = L,
                                                         useFeatures = use_features,
                                                         useChirality = use_chirality)
    return np.array(feature_list)
The use of pharmacophoric atom features makes FCFPs more specific to molecular interactions that drive biological activity. In certain molecular machine-learning applications, replacing ECFPs with FCFPs can therefore lead to increased performance and decreased learning time, as important high-level atomic properties are presented to the learning algorithm from the start and do not need to be inferred statistically. However, the standard atom features used in ECFPs contain more detailed low-level information that could potentially still be relevant for the prediction task at hand and thus be utilised by the learning algorithm. It is often unclear from the outset whether FCFPs will provide a substantial advantage over ECFPs in a given application; however, given how easy it is to switch between the two, it is almost always worth trying out both options.
[1] Weininger, David, Arthur Weininger, and Joseph L. Weininger. “SMILES. 2. Algorithm for generation of unique SMILES notation.” Journal of Chemical Information and Computer Sciences 29.2 (1989): 97-101.
[2] Rogers, David, and Mathew Hahn. “Extended-connectivity fingerprints.” Journal of Chemical Information and Modeling 50.5 (2010): 742-754.
The program cpptraj, written by Daniel Roe (https://github.com/Amber-MD/cpptraj) and distributed Open Source with the AmberTools package (https://ambermd.org/AmberTools.php), is a powerful tool for analysis of molecular dynamics simulations. In addition to all of the expected analyses like Root Mean Square Deviation and native contacts, cpptraj also includes a suite of vector algebra functions.
While this vector algebra functionality is fairly well known and easy to find in the documentation, I think it is less well known that cpptraj can write trajectories of the computed vectors. These trajectories can then be loaded into Visual Molecular Dynamics (VMD) alongside the analysed trajectory and played as a movie. This functionality is a valuable tool for debugging your vector calculations to make sure they are doing precisely what you intend. It may also prove useful for generating visualizations of vectors alongside molecular structures for publications.
The cpptraj script below reads in an Amber parameter file and coordinate file and then calculates the angle between two planes.
The first plane is defined by two vectors in the plane of the guanidino group of a R65 residue (v1 and v2); the second plane is defined by two vectors between CA atoms of amino acids in the alpha helix containing R65 (v3 and v4). The first two vectormath calls determine the normal vectors to the planes and the final vectormath line computes the angle between the normal vectors. Taken together, these commands compute the angle between the arginine side chain and a plane passing through the CA atoms of the alpha helix. Let’s check that the vectors {v1, v2, v3, v4} are being computed correctly.
The resulting vector trajectory vectors.mol2 can be loaded directly into VMD without a topology. Note that in this case we only analyzed a single frame, but you can run this same procedure on DCD files, too. This is what I get when I load the vectors into VMD alongside the structure:
The vectors are shown as red/pink line segments. The right structure is identical to the left but with the alpha helix cartoon model removed. The blue spheres indicate the locations of the CA atoms used to define the plane of the helix.
I hope this vector trajectory functionality will be helpful to a few people who like to neurotically check their analyses like I do. You can download the example prmtop and rst7 files below. Note that you should rename them to remove the extra “.txt” file extension before attempting to use them for anything.
The information in this blog post is adapted from an Amber Archive post from Daniel Roe, dated 30-Oct-2018: http://archive.ambermd.org/201811/0058.html
The Rectified Linear Unit (ReLU) activation function was first used in 1975, but its use exploded when it was used by Nair & Hinton in their 2010 paper on Restricted Boltzmann Machines. ReLU and its derivative are fast to compute, and it has dominated deep neural networks for years. The main problem with the activation function is the so-called dead ReLU problem, where significant negative input to a neuron can cause its gradient to always be zero. To rectify this (har har), modified versions have proposed, including leaky ReLU, GeLU and SiLU, wherein the gradient for x < 0 is not always zero.
A 2020 paper by Naizat et al., which builds upon ideas set out in a 2014 Google Brain blog post seeks to explain why ReLU and its variants seem to be better in general for classification problems than sigmoidal functions such as tanh and sigmoid.
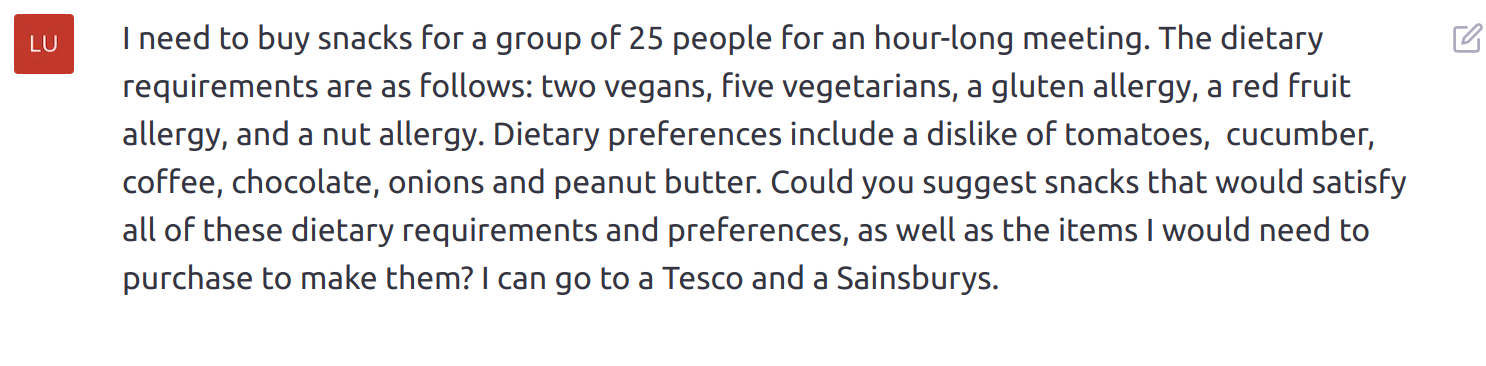
One of the most treasured group meeting institutions in OPIG is snackage. Each week, one group member is asked to bring in treats for our sometimes lengthy 16:30 meeting. However, as would be the case for any group of 25 or so people, there are various dietary requirements and preferences that can make this snack-quisition a somewhat tricky process: from gluten allergies to a mild dislike of cucumber, they vary in importance, but nevertheless are all to be taken into account when the pre-meeting supermarket sweep is carried out.
So, the question on every researcher’s mind: can ChatGPT help me? Turns out, yes: I gave it a list of the group’s dietary requirements and preferences, and it gave me a handy little list of snacks I might be able to bring along…
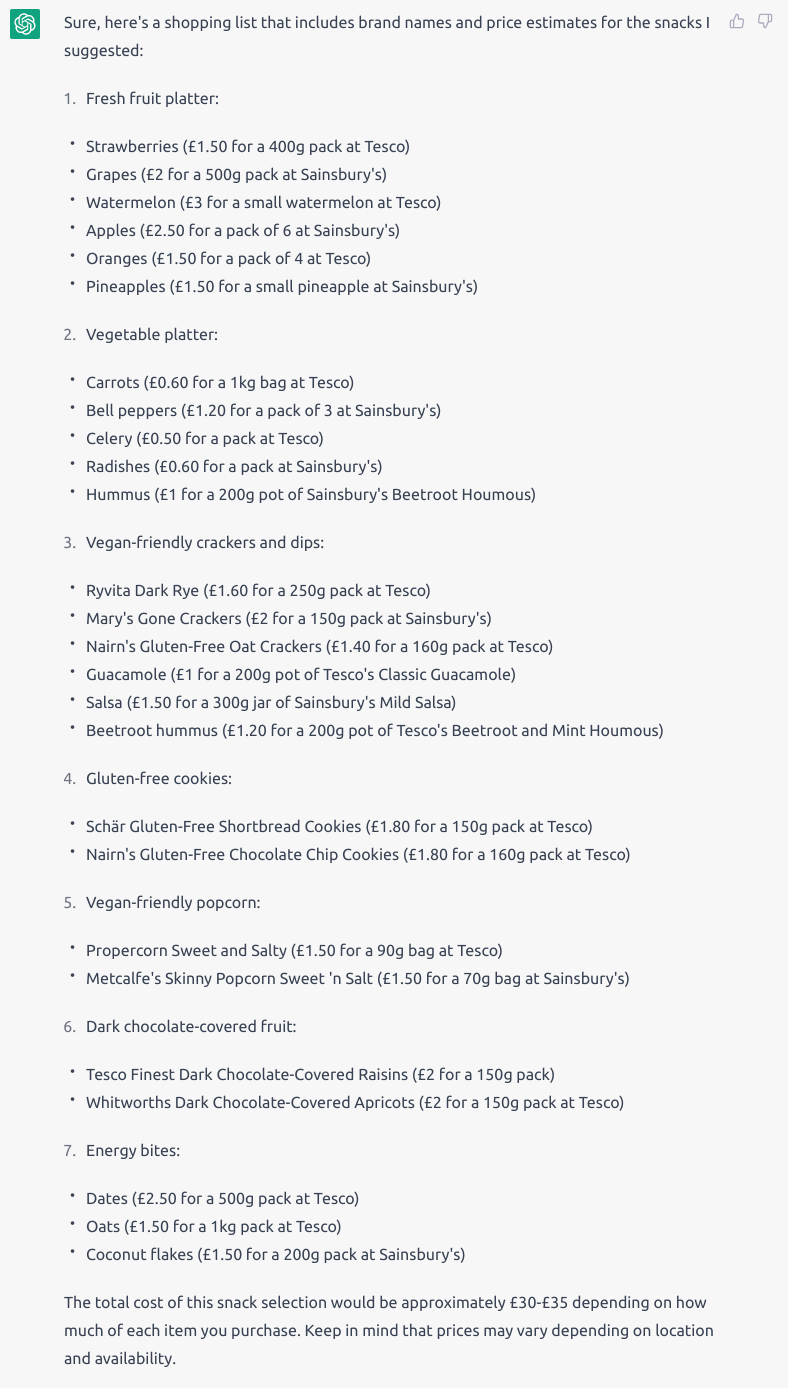
When pushed further, it even provided me with an itemised list of the ingredients required. During this process it seemed to forget a couple of the allergies I’d mentioned earlier, but they were easy to spot; almost more worryingly, it suggested I get a beetroot and mint hummus (!) for the veggie platter:
I don’t know if I’ll actually be using many of these suggestions—judging by the chats I’ve had about the above list, I think bringing in a platter of veggies as the group meeting snack may get me physically removed from the premises—but ChatGPT has once again proven itself a handy tool for saving a few minutes of thinking!
When engineering antibodies into effective biotherapeutics, ideally, factors such as affinity, specificity, chemical stability and solubility should all be optimised. In practice, we know that it’s often not feasible to co-optimise all of these, and so compromises are made, but identifying these developability issues early on in the antibody drug discovery process could save costs and reduce attrition rates. For example, we could avoid choosing a candidate that expresses poorly, which would make it expensive to manufacture as a drug, or one with a high risk of aggregation that would drive unwanted immunogenicity.
On this theme, I was interested to read recently a paper by the Computational Chemistry & Biologics group at Merck (Evers et al., 2022 https://www.biorxiv.org/content/10.1101/2022.11.19.517175v1). They have developed a pipeline called SUMO (In SilicoSequence Assessment Using Multiple Optimization Parameters), that brings together publicly-available software for in silico developability assessment and creates an overall developability profile as a starting point for antibody or VHH optimisation.
For each sequence assessed, they report factors such as sequence liabilities (residues liable to chemical modifications that can alter properties such as binding affinity or aggregation propensity), surface hydrophobicity, sequence identity compared to most similar human germline and predicted immunogenicity (based on MHC-II binding). Also provided are an annotated sequence viewer and 3D visualisation of calculated properties. Profiles are annotated with a red-yellow-green colour-coding system to indicate which sequences have favourable properties.
Overall, this approach is a useful way to discriminate between candidates and steer away from those with major developability issues prior to the optimisation stage. Given that the thresholds for their colour-coding system are based on data from marketed therapeutic antibodies, and that the software used has primarily been designed for use on antibody datasets, I would be interested to see whether the particular descriptors chosen for SUMO translate well to VHHs, or whether there are other properties that are stronger indicators of nanobody developability.
I am not sure the University of Oxford logo works in the gold from the University of Otago…
A few months back I moved from the Oxford BRC to OPIG, both within the university of Oxford, but like many in academia I have moved across a few universities. As this is my first post here I wanted to do something neat: a JS tool that swapped colours in university logos! It was a rather laborious task requiring a lot of coding, but once I got it working, I ended up tripping up at the last metre. So for technical reasons, I have resorted to hosting it in my own blog (see post), but nevertheless the path towards it is worth discussing.
Personal websites are a great and increasingly important way to build your online presence. Along with professional social media pages, such as on LinkedIn and Twitter, a website can provide a boost to your career and/or job search.
This blog post is based on my recent experience creating a personal website, following guidelines from Lewis’ talk at the OPIG Retreat last year (thank you Lewis!). The method I used and will cover here, based on an HTML5 UP! template and GitHub pages, is free and fast.
Why have a personal website?
Improves your online presence and brand
Boost for your career, including by allowing potential future employers to find you
Share things you have accomplished or are interested in
Now that machine learning has managed to get its proverbial fingers into just about every pie, people have started to worry about the generalisability of methods used. There are a few reasons for these concerns, but a prominent one is that the pressure and publication biases that have led to reproducibility issues in the past are also very present in ML-based science.
The Center for Statistics and Machine Learning at Princeton University hosted a workshop last July highlighting the scale of this problem. Alongside this, they released a running list of papers highlighting reproducibility issues in ML-based science. Included on this list are 20 papers highlighting errors from 17 distinct fields, collectively affecting a whopping 329 papers.
Websites store cookies to enhance functionality and personalise your experience. You can manage your preferences, but blocking some cookies may impact site performance and services.
Essential cookies enable basic functions and are necessary for the proper function of the website.
Name
Description
Duration
Cookie Preferences
This cookie is used to store the user's cookie consent preferences.
30 days
These cookies are used for managing login functionality on this website.
Name
Description
Duration
wordpress_logged_in
Used to store logged-in users.
Persistent
wordpress_sec
Used to track the user across multiple sessions.
15 days
wordpress_test_cookie
Used to determine if cookies are enabled.
Session
Statistics cookies collect information anonymously. This information helps us understand how visitors use our website.
Google Analytics is a powerful tool that tracks and analyzes website traffic for informed marketing decisions.
Contains information related to marketing campaigns of the user. These are shared with Google AdWords / Google Ads when the Google Ads and Google Analytics accounts are linked together.
90 days
__utma
ID used to identify users and sessions
2 years after last activity
__utmt
Used to monitor number of Google Analytics server requests
10 minutes
__utmb
Used to distinguish new sessions and visits. This cookie is set when the GA.js javascript library is loaded and there is no existing __utmb cookie. The cookie is updated every time data is sent to the Google Analytics server.
30 minutes after last activity
__utmc
Used only with old Urchin versions of Google Analytics and not with GA.js. Was used to distinguish between new sessions and visits at the end of a session.
End of session (browser)
__utmz
Contains information about the traffic source or campaign that directed user to the website. The cookie is set when the GA.js javascript is loaded and updated when data is sent to the Google Anaytics server
6 months after last activity
__utmv
Contains custom information set by the web developer via the _setCustomVar method in Google Analytics. This cookie is updated every time new data is sent to the Google Analytics server.
2 years after last activity
__utmx
Used to determine whether a user is included in an A / B or Multivariate test.
18 months
_ga
ID used to identify users
2 years
_gali
Used by Google Analytics to determine which links on a page are being clicked
30 seconds
_ga_
ID used to identify users
2 years
_gid
ID used to identify users for 24 hours after last activity
24 hours
_gat
Used to monitor number of Google Analytics server requests when using Google Tag Manager
1 minute
Google reCAPTCHA helps protect websites from spam and abuse by verifying user interactions through challenges.
Name
Description
Duration
_GRECAPTCHA
Google reCAPTCHA sets a necessary cookie (_GRECAPTCHA) when executed for the purpose of providing its risk analysis.