Vim and I

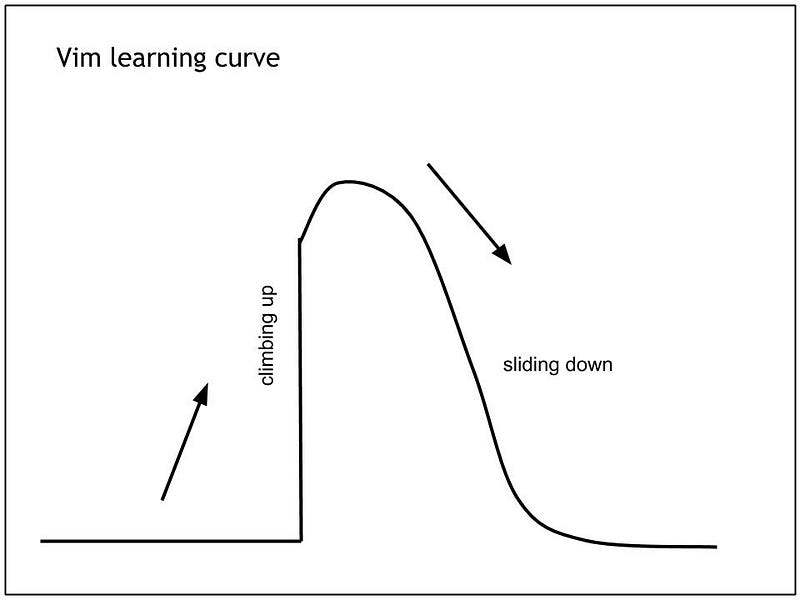
Vim is great. Despite its steep learning curve , it has many advantages and many loyal Vim followers will tell you that you should force yourself to use it.

Personally I started using Vim when I was ssh-ing into the group servers or into my computer in department. In such scenarios, I could not open the IDEs with the nice GUIs 🙁 However, as time passed, Vim started to grow on me. Now, I can list a few reasons why I think it is great, for example, it requires a small amount of memory to run, has a short start up time and can handle large files pretty well. 

Although, I am definitely not a Vim expert, I will tell you about some of the things I have added to my .vimrc. The .vimrc file is very handy for containing all your favourite settings, such as key mappings, custom commands, formatting and syntax highlighting. The file uses vimscript which is a programming language in itself. However, there is a lot of help online that tells you with what lines to add to your .vimrc. I would recommend installing Vundle which is a Vim plugin manager. 

Here I will list some cool things that I have discovered you can do with your .vimrc.   It has certainly made my life a bit nicer.

  1. Code Folding
    Most IDEs provide a way to collapse functions and classes that results in only seeing the function/class definition and hiding the code. To do this in Vim add the following lines to your .
    vimrc 

    " Enable folding
    set foldmethod=indent
    set foldlevel=99
    " Enable folding with the spacebar
    nnoremap <space> za


    Alternatively, you can install the Vim plugin SimpylFold.

  2. Python indentation
    Vim does not do auto indention like many IDEs. To automatically do PEP-8 indentation for Python, add the following to your .vimrc . 

    " PEP indentation
    au BufNewFile,BufRead *.py
    \ set tabstop=4    
    \ set softtabstop=4    
    \ set shiftwidth=4    
    \ set textwidth=79    
    \ set expandtab    
    \ set autoindent    
    \ set fileformat=unix
    

    You can also install the Vim plugin vim-flake8 which is a static syntax and style checker for Python source code. It shows errors in a quickfix window and lets you jump to their location inside your code.

  3. Turn line numbers on 
    Rather than typing in  
    :set nu 
    every time you open your files. You can always have them turned on by adding :set nu to your .vimrc
  4. Autocompletion 
    When I switch from PyCharm to Vim I feel a bit lost without the autocompletion however, after a quick search I found many are using the Vim package Youcompleteme and it is awesome. 
Exciting new studies in OAS

Hi everyone!

Today is the day for another blog post from me. Here, I would like to give you an update on new studies, which were deposited in the Observed Antibody Space (OAS) resource and take a closer look at one of these studies. To date, we have curated 57 studies in OAS, where we provide raw nucleotide and numbered amino acid sequences for download. These amino acid sequences have been filtered using ANARCI parsing, which ensures that the sequences align to respective species HMM profiles and do not have unusual indels and frameshifts. More than 660 million numbered amino acid sequences are deposited in OAS, where every sequence keeps a link to its corresponding nucleotide sequence. Recently we added two more studies to OAS: Sheng et al., (2017) and Setliff et al., (2018). We numbered roughly 2.8 and 46 million sequences in Sheng et al., and Setliff et al., studies respectively. In this blog post, I would like to talk more about the uniqueness of Setliff et al., data.

Continue reading →

Finding the lowest energy conformation of given molecule!

Generating low-energy molecular conformers is important for many areas of computational chemistry, molecular modeling and cheminformatics. Many tools have been developed to generate conformers, including BALLOON (1), Confab (2), FROG2 (3),  MOE (4), OMEGA (5) and RDKit (6). The search algorithm implemented in these tools can be broadly classified as either systematic or stochastic. These algorithms primarily focus on generating geometrically diverse low-energy conformers. Here, we are interested in finding lowest energy conformation of a molecule instead of achieving geometric diversity and Bayesian optimization is used to find the lowest energy conformation (7). Continue reading →

Check My Blob

A brief overview and discussion of: Automatic recognition of ligands in electron density by machine learning .This paper aims to reduce the bias of crystallographers fitting ligands into electron density for protein ligand complexes. The authors train a supervised machine learning model using known ligand sites across the whole protein databank, to produce a classifier that can identify which common ligands could fit to that electron density.

Continue reading →

OPIG Putts Up

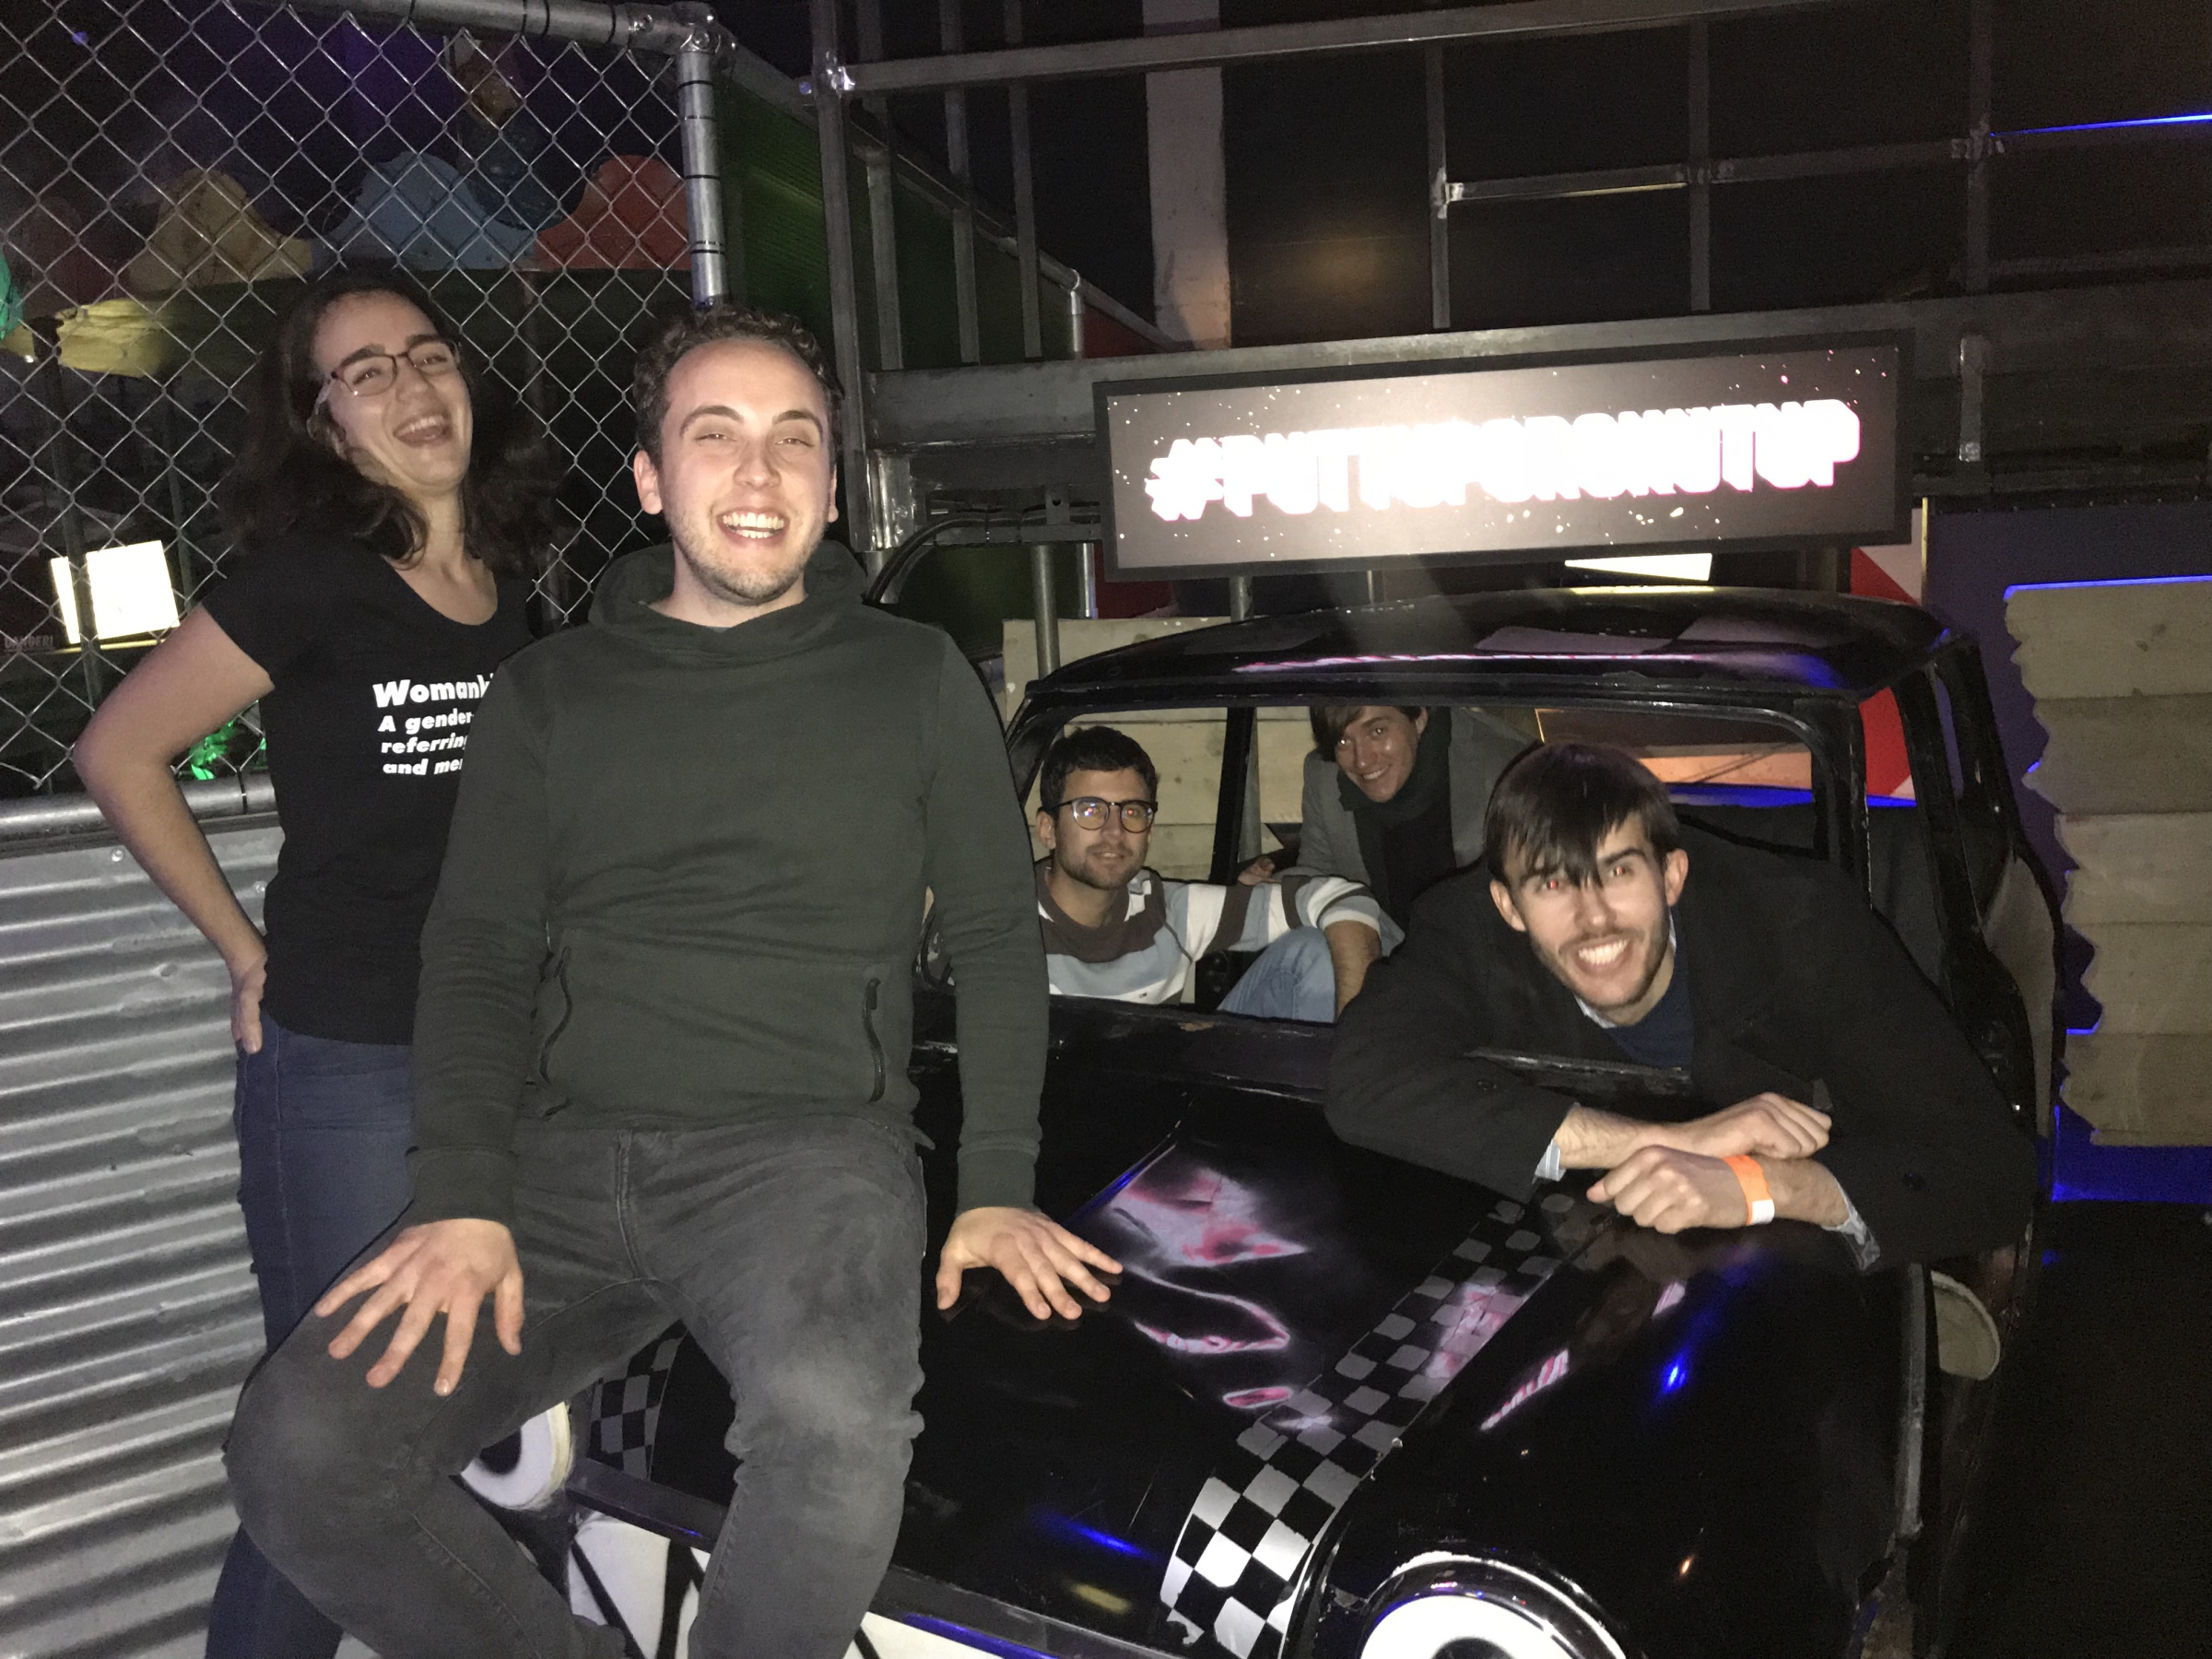
Tonight, post-OPIG Group Meeting, most of us visited the local crazy golf course “Junkyard Golf” for some serious fun. Three groups of us teed off at different times, negotiating dimly lit Heath-Robinson/Rube Goldberg-style courses leading into bathtubs, past bears and through volcanoes. We’re not competitive at all (Serenity & Crunch) so it was a great surprise to learn at the end of our games that CW had won…

Post-putting OPIGlets

Image 1 of 5

What can you do with the OPIG Antibody Suite?

OPIG has now developed a whole range of tools for antibody analysis. I thought it might be helpful to summarise all the different tools we are maintaining (some of which are brand new, and some are not hosted at opig.stats), and what they are useful for.

Immunoglobulin Gene Sequencing (Ig-Seq/NGS) Data Analysis

1. OAS
Link: http://antibodymap.org/
Required Input: N/A (Database)
Paper: http://www.jimmunol.org/content/201/8/2502

OAS (Observed Antibody Space) is a quality-filtered, consistently-annotated database of all of the publicly available next generation sequencing (NGS) data of antibodies. Here you can:

Continue reading →

docopt for dummies

Parsing command line arguments is an annoying piece of boilerplate we all have to do. Documenting our code is either an absolutely essential part of software engineering, or a frivolous waste of research time, depending on who you ask. But what if I told you that we can combine the two? That you can handle your argument parsing simply by documenting how your code works? Well, the dream is now reality. Continue reading →

How to get seasick without leaving your desk

It’s always easy to get caught up in computational work, so let me describe a quick experiment you can do to relieve the boredom. Sit down in your spinny chair and cross your legs. (You do have a spinny chair, right? If not, get one – they prevent repetitive strain injuries, and more importantly, they are great fun. This experiment works best if the chair has no arms.) Start spinning that spinny chair until you feel like you’ve achieved a stable rotation. Then – smartly – stop the rotation and sit up straight. Continue reading →

Preparing a five minute conference talk: an honest account

On 26 September I had the opportunity to give a short talk at the COSTNET18 conference in Warsaw. I’d never done anything like it before, which made it both exciting and a tiny bit terrifying. I thought I’d share how I prepared for it, in the hope that other conference newbies might find some of it useful, or at least funny.

20 July

I register for the conference, and apply to give a talk. I use a version of my paper draft abstract, to which I add a couple of introductory sentences. I submit successfully, but at the end of the day accidentally delete this version of the abstract from my computer. I guess if I need it, I just need to wait until the conference programme becomes available. #fail Continue reading →

So, you are interested in compound selectivity and machine learning papers?

At the last OPIG meeting, I gave a talk about compound selectivity and machine learning approaching to predict whether a compound might be selective. As promised, I hereby provide a list publications I would hand to a beginner in the field of compound selectivity and machine learning.  Continue reading →